Running Apache Spark with sparklyr and R in Windows
RStudio recently released the sparklyr package that allows users to connect to Apache Spark instances from R. In addition, this package offers dplyr integration, allowing you to utilize Spark as you use dplyr functions like filter and select, which is very convenient. The package will also assist you in downloading and installing Apache Spark if it is a fresh install. This post covers the local install of Apache Spark via sparklyr and RStudio in Windows 10.
As per the guide, install the latest preview release of RStudio and run the following commands to install sparklyr
1install.packages("devtools")
2devtools::install_github("rstudio/sparklyr")
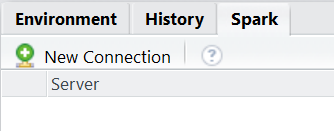
Once installed, you should see a new tab beside Environment and History tabs in RStudio - the Spark tab. You will be able to see a “New Connection” button.
On clicking the button, you will be able to set various options from Spark and Hadoop versions (at time of writing - Spark 1.6.2 and Hadoop 2.6) to connecting to local or remote Spark clusters and whether to use dplyr as the DB interface. Let’s use the defaults here.
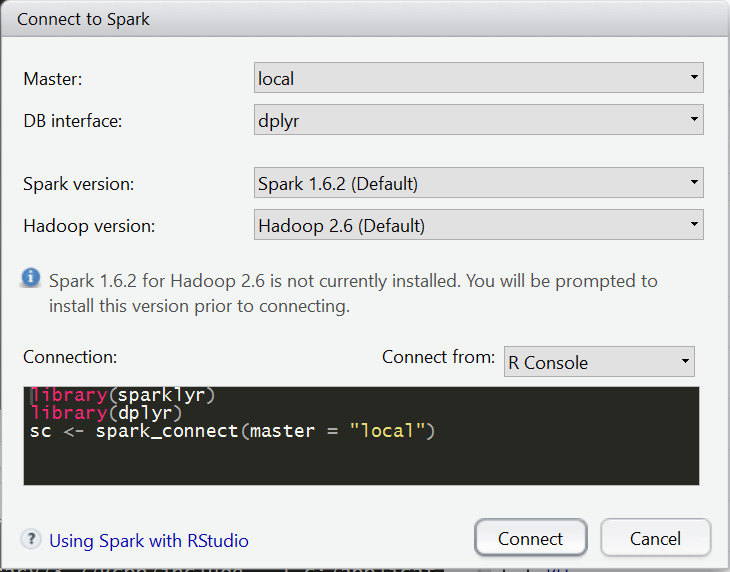
If this is a fresh install, RStudio will prompt a confirmation dialog box:

Upon clicking “Install”, RStudio will then proceed to download and install Apache Spark for you and attempt to connect to the local Spark instance.
At this stage you might receive a similar error message below:
1Error in start_shell(scon, list(), jars, packages) :
2  Failed to launch Spark shell. Ports file does not exist.
3    Path: C:\Users\<USERNAME>\AppData\Local\rstudio\spark\Cache\spark-1.6.2-bin-hadoop2.6\bin\spark-submit.cmd
4    Parameters: --packages "com.databricks:spark-csv_2.11:1.3.0,com.amazonaws:aws-java-sdk-pom:1.10.34" --jars "<PATH TO R PACKAGES>\R\win-library\3.2\sparklyr\java\rspark_utils.jar"  sparkr-shell D:\Temp\RtmpO0cLos\file23c0703c73bf.out
5
6In addition: Warning message:
7running command '"C:\Users\<USERNAME>\AppData\Local\rstudio\spark\Cache\spark-1.6.2-bin-hadoop2.6\bin\spark-submit.cmd" --packages "com.databricks:spark-csv_2.11:1.3.0,com.amazonaws:aws-java-sdk-pom:1.10.34" --jars "<PATH TO R PACKAGES>\R\win-library\3.2\sparklyr\java\rspark_utils.jar"  sparkr-shell <PATH TO TEMP DIRECTORY>\Temp\RtmpO0cLos\file23c0703c73bf.out' had status 127
If you meet this error, it may be due to Windows security permissions of the .CMD files for Apache Spark. To resolve this issue, go to the Apache Spark install directory, which should be C:\Users\<USERNAME>\AppData\Local\rstudio\spark\Cache\spark-1.6.2-bin-hadoop2.6\bin\. You should be able to see the files ending with extension .cmd. At the time of writing, the files include
 1beeline.cmd
 2load-spark-env.cmd
 3pyspark.cmd
 4pyspark2.cmd
 5run-example.cmd
 6run-example2.cmd
 7spark-class.cmd
 8spark-class2.cmd
 9spark-shell.cmd
10spark-shell2.cmd
11spark-submit.cmd
12spark-submit2.cmd
13sparkR.cmd
14sparkR2.cmd
For each of the these .CMD files, edit the security permission for your USERNAME to allow “Read & execute” as shown below:
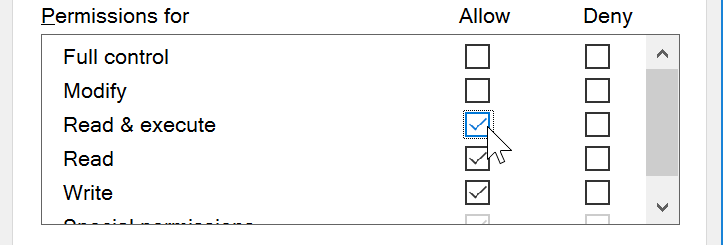
After editing the permissions, when you attempt to connect to Spark by running the commands below, you should not experience any more errors.
1> library(sparklyr)
2> library(dplyr)
3> sc <- spark_connect(master = "local")
To verify, you can try out the examples from the RStudio guide, or try the adapted example below:
 1> iris_tbl <- copy_to(sc, iris)
 2> iris_tbl
 3Source:   query [?? x 5]
 4Database: spark connection master=local app=sparklyr local=TRUE
 5
 6   Sepal_Length Sepal_Width Petal_Length Petal_Width Species
 7          <dbl>       <dbl>        <dbl>       <dbl>   <chr>
 81           5.1         3.5          1.4         0.2  setosa
 92           4.9         3.0          1.4         0.2  setosa
103           4.7         3.2          1.3         0.2  setosa
114           4.6         3.1          1.5         0.2  setosa
125           5.0         3.6          1.4         0.2  setosa
136           5.4         3.9          1.7         0.4  setosa
147           4.6         3.4          1.4         0.3  setosa
158           5.0         3.4          1.5         0.2  setosa
169           4.4         2.9          1.4         0.2  setosa
1710          4.9         3.1          1.5         0.1  setosa
18# ... with more rows
19>
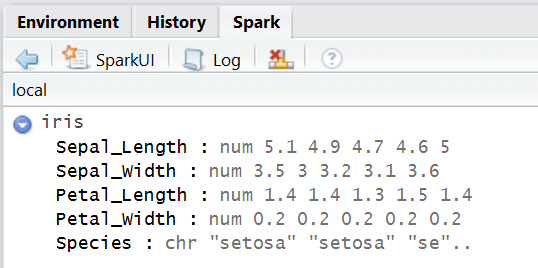
Visually, you would be able to see the data frame in the Spark tab as well:
You can now have fun with Apache Spark in RStudio! You might also want to add the Apache Spark install directory C:\Users\<USERNAME>\AppData\Local\rstudio\spark\Cache\spark-1.6.2-bin-hadoop2.6\bin to your path so that you can run Spark shells ( sparkr, pyspark and spark-shell) in the command line. For example, with PySpark, you should see a similar welcome screen as below after the initialization messages.